arXiv 2026
WorldBagel: Uncovering the Power of Unified Multimodal Models for Vision-Language-Action-World Modeling
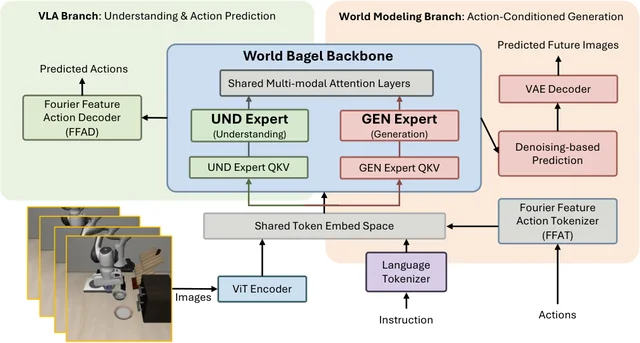
WorldBagel is a unified Vision-Language-Action-World (VLAW) framework built on BAGEL that systematically investigates the role of unification in world modeling. On LIBERO, Language Table, and Franka, it consistently outperforms task-specific alternatives and learns action representations that are more structured and semantically aligned with visual and linguistic context.